An automation is not dependable merely because it completed yesterday.
The connection can expire. A destination can accept a new record and fail before returning confirmation. A later step can break after an earlier step changed something. The alert can go to an inbox nobody owns. A well-meaning person can press Retry and create the same work twice.
A useful automation failure plan answers five questions before that happens:
- What evidence shows what the run attempted?
- Which failures require a person to act?
- Who owns that action?
- When is a retry safe?
- What proves the business outcome recovered?
This article provides an operational starting point for an ordinary business workflow. It does not promise uninterrupted service or prescribe one platform’s settings for every system. The exact failure modes, retry guarantees, notification behavior, retention, and recovery controls depend on the tools and APIs involved.
Follow one hypothetical workflow
Consider a fictional small business with this scheduled workflow:
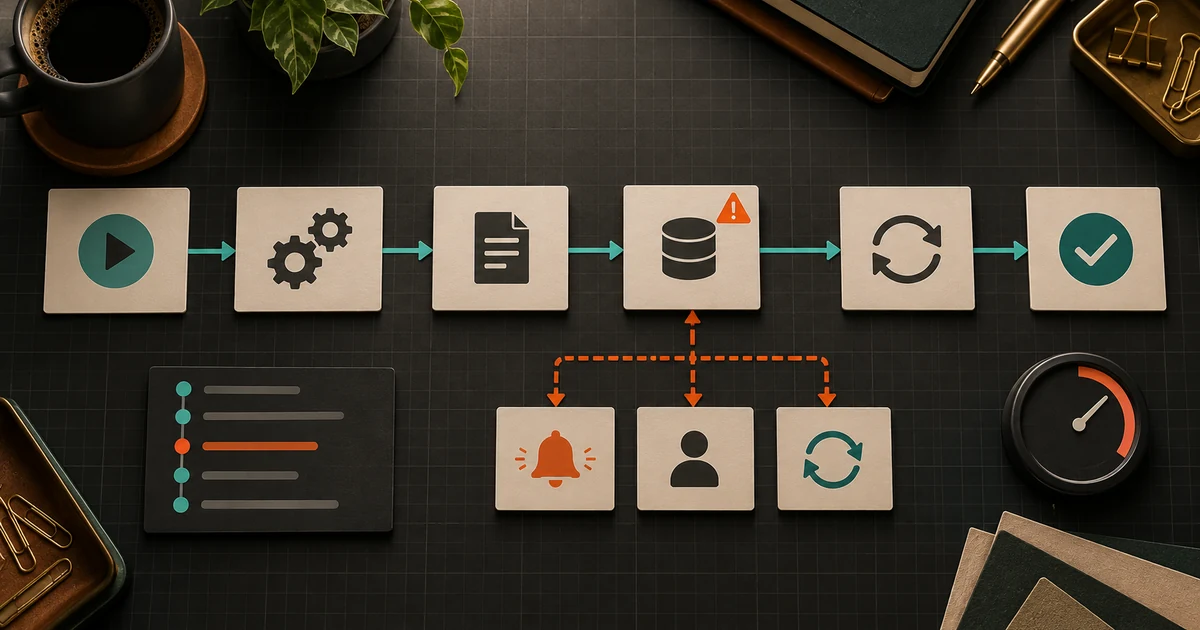
At 7:00 each morning, the automation reads approved request rows, creates one work item for each eligible row, writes the new work-item reference back to the row, and sends the operations owner a summary.
This workflow and business are hypothetical. They are not a Fireproof Studio customer result or a description of a live Fireproof system.
The happy path is easy to describe. The failure path is not.
- What if the schedule never starts?
- What if the source is available but the destination is not?
- What if a work item is created but its reference is not written back?
- What if the run finishes but the summary fails?
- What if the same row is processed again?
“Failed” is not one condition. A run may fail before changing anything, after completing part of the job, or after completing the job but before recording enough evidence to prove it. That last state is unknown, not automatically safe to retry.
Copy this automation failure-plan matrix
Build the matrix around the actual steps and consequences in one workflow. Do not copy the example pass conditions without adapting them to the tools you use.
On a narrow screen, swipe the table horizontally to read every column.
| Step | Expected result | Evidence to retain | Failure signal | Retry decision | Recovery owner | Proof of recovery |
|---|---|---|---|---|---|---|
| Scheduled start | One run begins for the expected window | Run ID, scheduled time, actual start time, workflow version | No run appears by the agreed check time | Start only after confirming another run is not active or delayed | Workflow owner | One bounded run exists for the window |
| Read eligible rows | The run identifies the intended test or business records | Input references, selection rule, count, timestamp | Source error, permission failure, or unexpected count | Retry only if the read has no downstream side effect and the source state is understood | Process owner | Eligible set is recorded and reviewed |
| Create work item | One intended item is created for each eligible row | Source reference, destination reference, attempt ID, result | Error, timeout, or missing confirmation | Reconcile destination before retrying an uncertain request | System owner | Intended item exists once with the expected content |
| Write destination reference | The source row records the created item | Source reference, destination reference, update status | Created item exists but source update failed | Repair the reference; do not recreate the item | Data owner | Source and destination references agree |
| Send summary | The owner receives an accurate run result | Delivery status, run link, counts, unresolved items | Delivery error or missing summary | Resend the summary, not the business actions | Operations owner | Owner can see the run result and remaining work |
| Close recovery | The original business outcome is complete | Final disposition, verifier, time, exceptions | Work was changed but not rechecked | Do not close until the original scenario is exercised | Process owner | Expected records exist once and open exceptions are assigned |
The matrix separates the failed technical step from the business outcome. A red run status may still leave completed work behind. A green retry may still duplicate something created during the first attempt. Recovery begins by establishing the current state, not by making the status indicator green.
Keep a run record that supports a decision
A useful run history should let the owner reconstruct what happened without guessing. For this hypothetical workflow, the record would need enough information to answer:
- Which workflow version and run attempted the work?
- When did it start and stop?
- Which source references were eligible?
- Which step completed last?
- What error or timeout was reported?
- Which destination references were returned?
- How many retries occurred?
- Was the final disposition successful, failed, partially complete, or unknown?
Keep the record proportional to the workflow. Do not copy secrets, full customer records, or unnecessary sensitive data into an error log merely to make debugging easier. Record stable references and the minimum context required to investigate through the approved systems.
Microsoft’s current Power Automate guidance provides a platform-specific example. Its monitoring documentation describes built-in views of flow runs, errors, and execution details, while its error-handling guidance shows how a flow can capture run information and link directly to a run. Those features describe Power Automate, not every automation platform. Verify the history, access, and retention available in your own tool.
Alert the person who can act
An alert is useful when it reaches a named owner with enough context to make a decision. “Automation failed” is a status. It is not a recovery instruction.
Include:
- the workflow and affected run;
- the first meaningful failed step, not every downstream symptom;
- the known or possible business impact;
- whether any side effect may already have occurred;
- the current retry state;
- the named owner and escalation route;
- a link to the run record and recovery instructions;
- the next safe action, when one is known.
Google’s Site Reliability Engineering guidance on monitoring distributed systems distinguishes symptoms from causes and argues that alerts which interrupt a person should be urgent and actionable. A small business may not operate a pager or an SRE team, but the editorial lesson still applies: notify a person when that person has a reason and a way to act. Put lower-urgency conditions in a review queue or dashboard instead of making every imperfect run an emergency.
Do not assume the platform’s default email covers every failure. In Power Automate specifically, Microsoft documents that per-run failure notifications target certain failures for which the service identifies a known fix; other failure types remain visible in monitoring and run history. The same documentation describes recipient rules, a cooldown between per-run alerts for the same flow, and a weekly digest. Those are current Power Automate behaviors, not general automation rules. They are a reason to test the exact alert path instead of treating the presence of an email setting as coverage proof.
Test the notification as its own handoff. Confirm who receives it, what happens during that person’s absence, where unresolved failures remain visible, and how the owner records that investigation has begun.
Classify the result before retrying
Before any retry, place the failed action in one of four states:
- No side effect occurred. Evidence shows the destination rejected or never received the operation.
- The operation is designed for a safe repeat. The interface provides a documented idempotency mechanism and the retry uses it correctly.
- A side effect occurred. The destination shows the intended result, even though a later step failed.
- The outcome is unknown. The request may have completed, but confirmation or evidence is missing.
Only the first two states are candidates for an automatic retry, and only within the limits supported by the exact system. The third needs recovery from the next incomplete step. The fourth needs reconciliation before another mutating request.
The AWS Builders’ Library article on idempotent APIs explains why a timeout can leave a caller unsure whether an operation completed. It describes an idempotent operation as one that can be retried without additional side effects and presents caller-provided request identifiers as one design for recognizing repeated intent.
That is a design pattern, not permission to retry every API request. The receiving API must document and correctly implement the behavior. Two requests with the same fields are not necessarily duplicates, and an identifier reused for a different intent can be wrong. For a no-code workflow or third-party connector, check the connector and destination documentation rather than assuming the platform makes the operation idempotent.
Bound automatic retries
Retries can recover from a temporary problem. They can also repeat a permanent error, increase load on an unavailable service, delay the alert, or create duplicate work when the original outcome is uncertain.
Define the boundary before enabling them:
- which errors are considered temporary;
- which actions are safe to repeat;
- the maximum number of attempts;
- the delay or backoff between attempts;
- the point at which a person is alerted;
- the evidence retained for every attempt;
- the stop condition when the outcome is unknown.
Power Automate’s error-handling guidance documents configurable retry policies for actions, including fixed and exponential intervals and a maximum retry count. That is one platform’s control surface. Other tools may expose different options or implement retries below the layer you can see. Read the current documentation for the exact action and destination.
Never use repeated retries to hide a broken credential, invalid input, changed schema, revoked permission, or unsupported request. Those failures need correction or escalation, not more attempts.
Give recovery to one named owner
“The team” is not a recovery owner. Assign a primary role and a backup role that have the access and context required to act.
The recovery sequence should be short enough to use under pressure:
- Pause or contain additional runs when continued execution could add harm.
- Preserve the failed run record and exact error.
- Reconcile completed side effects in the destination.
- Classify each affected item as complete, incomplete, or unknown.
- Choose a safe retry, a resume from the next step, or a bounded manual repair.
- Execute the chosen path once with recorded identifiers.
- Re-run the original business scenario and inspect the result.
- Check an adjacent risk, such as duplicate creation or a missed item.
- Record the final disposition and any still-unresolved work.
A manual correction can restore one record. It does not prove the automation is repaired. Keep those conclusions separate. If the code, configuration, or connection changed, repeat the failure-shaped test against the changed workflow before returning it to normal operation.
The ownership questions are similar to a broader technology handoff. Fireproof Studio’s website ownership checklist shows how to separate account control, maintenance responsibility, and recovery authority instead of assuming one vague “owner” covers all three.
Rehearse the failure plan before it is needed
Use test records and a safe environment or test mode when the platform provides one. Do not deliberately break a live customer path merely to complete a checklist.
Exercise the failure shapes that matter:
- the scheduled trigger does not start;
- the source connection is unavailable;
- the destination rejects a request;
- the destination accepts a request but the next checkpoint fails;
- the alert cannot reach its primary owner;
- a retry is attempted with the same request identifier where the interface supports that contract;
- a retry must be stopped because the first outcome is unknown;
- the corrected workflow completes without missing or duplicating the test work.
Capture the environment, run identifiers, expected result, observed result, owner, and recovery evidence. A component test can prove one branch. It does not prove the complete business workflow recovered.
For customer-facing handoffs, the service website inquiry checklist applies the same discipline beyond the form: follow the event through delivery, assignment, response, and a truthful failure path.
Close on the business outcome
Recovery is complete when the intended work exists once, the owner can identify what happened, the original scenario succeeds, and every affected item has a final disposition. A cleared alert, successful retry status, or corrected row is supporting evidence—not the outcome by itself.
Start with one important automation. Fill in the matrix, trigger a safe failure, and follow the run from detection through verified recovery. The gaps you find will be more useful than another “successful” run that nobody can explain.
If an existing workflow is brittle or a new connection needs failure handling designed from the start, explore Fireproof Studio’s plugins and integrations service.